Problem
Strong coding models do not fit in 16 GB of VRAM, and when they fit, the desktop starts to stutter.
What I built
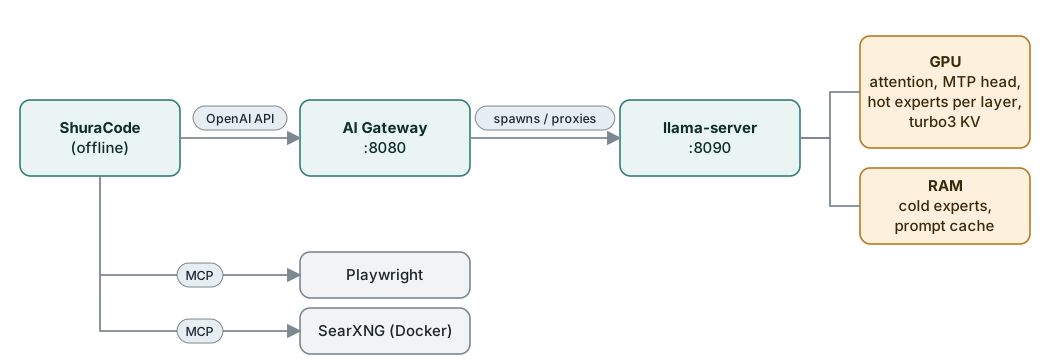
An OpenAI-compatible gateway in Python that loads the model on demand, survives crashes and saves long sessions. My own llama.cpp fork in C++ with an expert cache and a VRAM governor. A harness of 111 agentic coding tasks.
Result
78 tok/s on short context with MTP, up to 200k context, a 100k-token prompt read at about 1,000 tok/s. A 32k-token session restores in 0.14 s instead of 42 s. 580+ tests, CI on Linux, macOS and Windows.
Python · C++ · llama.cpp · ROCm / HIP · MCP · Docker